Machine learning is a branch of artificial intelligence that teaches computers to learn patterns from data instead of following hand-written rules. A machine learning model studies examples, finds the relationships inside them, and then uses what it learned to make predictions or decisions about new data it has never seen.

You already use machine learning dozens of times a day. It filters spam out of your inbox, suggests the next show on your streaming app, flags an odd card payment, and turns your voice into text.

This guide explains what machine learning is, how it works, what it is used for, and how the main machine learning algorithms and models differ. It is written for beginners, but it goes deep enough to help you choose the right approach for a real project.

What Is Machine Learning?

Machine learning (ML) is a way of building software that improves through experience. Instead of a programmer writing every rule, the system learns from examples and figures out the rules itself.

Think about a spam filter. A rule-based filter needs someone to list every suspicious word. A machine learning filter shows thousands of emails already marked “spam” or “not spam”. It learns which combinations of words, senders, and links predict spam, including ones no person thought to list.

The term dates back to 1959, when IBM researcher Arthur Samuel used it to describe a checkers program that learned to play better than the person who wrote it (IBM).

Machine Learning vs AI vs Deep Learning

These three terms are nested, not interchangeable. All machine learning is AI, but not all AI is machine learning.

Term

What it means

Everyday example

Artificial intelligence (AI)

The broad goal of making machines perform tasks that need human-like intelligence

A chess engine, a chatbot, a route planner

Machine learning (ML)

A subset of AI where systems learn patterns from data

A bank model that flags unusual payments

Deep learning

A subset of ML that uses many-layered neural networks

Face unlock on your phone

The practical difference between classic ML and deep learning is who picks the features. In traditional ML, people usually decide which inputs matter, such as an email’s sender or word count. Deep learning finds those features by itself, which is why it needs far more data and computing power.

Where Generative AI Fits In

Generative AI tools such as chatbots and image generators are built on machine learning. Most ML models predict or classify, for example, “Will this customer cancel?” Generative models learn the patterns in their training data so well that they can produce new text, images, or code that resembles it.

Google now groups ML systems into supervised, unsupervised, reinforcement, and generative AI (Google for Developers).

How Does Machine Learning Work?

Machine learning works by feeding an algorithm example data, letting it adjust itself to reduce its mistakes, and then testing it on data it has not seen. Most projects follow the same six steps:

  1. Define the problem. Decide what you want to predict, such as house prices or whether a payment is fraud.
  2. Collect and prepare data. Gather examples, remove errors and duplicates, and convert everything into numbers a computer can process.
  3. Choose an algorithm. Pick a learning method that suits the problem and the data you have.
  4. Train the model. The algorithm makes predictions on the training data, measures how wrong it is, and adjusts itself. It repeats this many times.
  5. Test and evaluate. Check accuracy on held-back data the model never saw during training.
  6. Deploy and monitor. Put the model to work and keep checking it, because real-world data drifts over time.

Training Data, Features and Labels

Three terms come up in every machine learning project:

  • Training data is the set of examples the model learns from.
  • Features are the input details in each example. For a house, features might be square footage, number of bedrooms, and ZIP code.
  • Labels are the correct answers, such as the price each house actually sold for. Not every type of ML needs labels.

Data quality matters more than most beginners expect. A model trained on biased or incomplete data will repeat those flaws at scale.

Training, Testing and Generalization

The real goal of machine learning is not to score well on training data. It is to perform well on new data, which is called generalization (IBM).

That is why teams split their data. A common split keeps about 80% for training and 20% for testing. If a model scores 99% on training data but 70% on test data, it has memorized the examples instead of learning the pattern. This problem is called overfitting.

What Is Machine Learning Used For?

Machine learning is used wherever there is a lot of data and a repeated decision: predicting outcomes, sorting information, spotting unusual activity, and personalizing what people see. Here is where you will find it.

Everyday Examples of Machine Learning

  • Recommendations. Netflix, Spotify and Amazon suggest shows, songs and products based on what you and similar users chose before.
  • Spam filters. Your email provider classifies incoming mail and learns from every message you mark as spam.
  • Voice assistants. Siri, Alexa and dictation apps convert speech to text and work out what you meant.
  • Face unlock. Apple’s Face ID uses machine learning for image recognition to unlock your phone (Built In).
  • Search engines and maps. Search ranking, autocomplete, and traffic-aware route times all rely on ML.

The UK’s Royal Society lists a similar set: search engines, spam filters, personalized recommendations, fraud detection in banking, and voice recognition on phones (Royal Society).

Finance and Banking

Banks train models to recognize suspicious transactions and send them for review (IBM). Lenders also use ML for credit decisions, and insurers use it for pricing.

In the UK, a joint Bank of England and FCA survey found ML use in financial services is still growing. Its case studies cover insurance pricing, credit underwriting, and fraud and anti-money laundering checks (Bank of England).

Healthcare

Machine learning helps clinicians read medical images, such as scans and X-rays, and flag cases that need a closer look. Hospitals also use it to predict patient outcomes and plan staffing. In these settings, ML supports doctors rather than replacing their judgment.

Retail, E-commerce and Marketing

Retailers use ML to forecast demand, set prices, and decide what stock to hold. Marketing teams use it to score leads, predict which customers may leave, and follow up with shoppers who abandon their carts.

Cybersecurity and Fraud Detection

Security tools learn what normal network and login activity looks like. When something breaks the pattern, such as a login from a new country at 3 a.m., the system raises an alert. This anomaly detection catches threats that fixed rules would miss.

Manufacturing, Transport and Logistics

Factories use sensor data to predict when a machine will fail, so they can fix it before it breaks. This is called predictive maintenance. Delivery companies use ML to plan routes, and self-driving systems use it to detect pedestrians, signs and other vehicles.

Types of Machine Learning

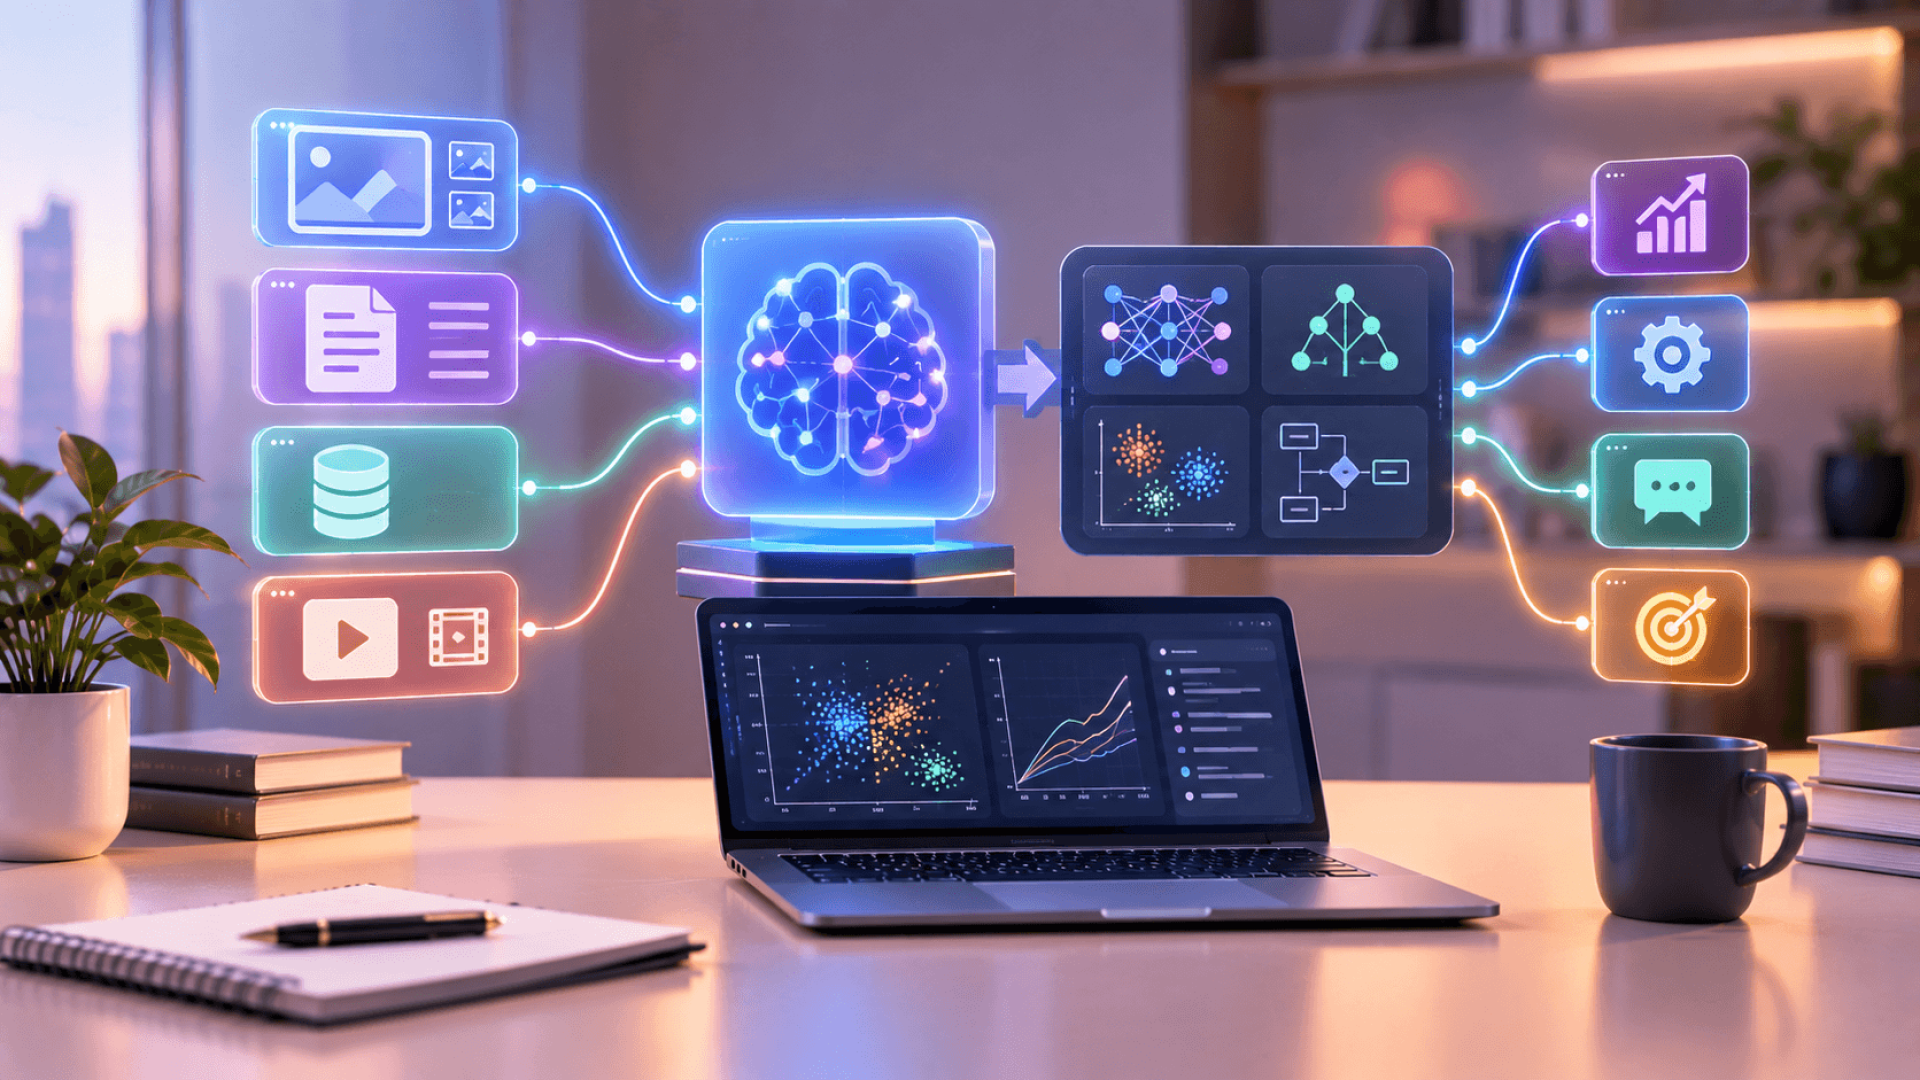
There are four core types of machine learning: supervised, unsupervised, semi-supervised and reinforcement learning. Self-supervised learning is now widely treated as a fifth. The type you use depends on one question: what kind of data and feedback do you have?

Type

Data it learns from

Typical task

Example

Supervised

Labeled examples

Predict or classify

Spam or not spam

Unsupervised

Unlabeled data

Find groups and patterns

Customer segments

Semi-supervised

A few labels, lots of unlabeled data

Classify when labeling is costly

Tagging medical images

Reinforcement

Rewards and penalties

Learn a sequence of actions

Game-playing agents, robots

Self-supervised

Unlabeled data that creates its own labels

Pre-train large models

Language models predicting the next word

Supervised Learning

Supervised learning trains a model on examples that already have the right answer. Google compares it to a student studying old exams that include both questions and answers (Google for Developers). It is the most common type in business and covers two jobs: classification (sorting into categories) and regression (predicting a number).

Unsupervised Learning

Unsupervised learning works with unlabeled data. The model looks for structure on its own, usually by grouping similar items. Retailers use it to discover customer segments they did not know existed.

Semi-Supervised Learning

Semi-supervised learning combines a small labeled dataset with a much larger unlabeled one. It is useful when labeling is slow or expensive, such as when only a specialist can tag each example.

Reinforcement Learning

Reinforcement learning trains an agent through trial and error. The agent takes actions, receives rewards or penalties, and gradually learns the strategy that earns the most reward. It has been used to train robots and programs like AlphaGo, which mastered Go.

Self-Supervised Learning

Self-supervised learning creates its own labels from raw data. For example, a language model hides a word in a sentence and learns by predicting it. This approach lets models learn from huge amounts of text and images, and it underpins today’s generative AI tools.

Machine Learning Algorithms vs Machine Learning Models: What’s the Difference?

A machine learning algorithm is the method used to learn from data. A machine learning model is what you get after you train that algorithm on a specific dataset. The algorithm is the recipe; the model is the finished dish.

For example, “decision tree” is an algorithm. When you train it on five years of your company’s sales data, you get a model that predicts next month’s sales. Train the same algorithm on hospital data, and you get a completely different model.


Machine learning algorithm

Machine learning model

What it is

A general procedure for learning patterns

A trained system built for one task

When it exists

Before training

After training

Depends on your data?

No, it is generic

Yes, it reflects the data it learned from

Example

Random forest

A random forest that predicts customer churn for one telecom firm

What you do with it

Choose it and tune its settings

Deploy it to make predictions

People often use the two terms loosely, and you will see “model” used for both. The distinction matters when you plan a project: you choose an algorithm, but you deploy, monitor, and retrain a model.

Common Machine Learning Algorithms

Most real-world projects rely on a short list of proven algorithms. The table gives a quick view; the sections below explain each one in plain English.

Algorithm

Learning type

Best for

Easy to explain?

Linear regression

Supervised

Predicting a number

Yes

Logistic regression

Supervised

Yes/no predictions

Yes

Decision tree

Supervised

Rules people can read

Yes

Random forest

Supervised

Accurate predictions on tabular data

Partly

Support vector machine

Supervised

Classification with clear margins

Partly

K-nearest neighbors

Supervised

Simple similarity-based predictions

Yes

K-means clustering

Unsupervised

Grouping unlabeled data

Yes

Gradient boosting

Supervised

Top accuracy on business data

Partly

Neural networks

Any

Images, speech, text

No

Linear Regression

Linear regression draws the best-fitting straight line through your data to predict a continuous value. It answers questions like “How much will this house sell for?” It is fast, simple, and a sensible first baseline for any numeric prediction.

Logistic Regression

Despite its name, logistic regression is used for classification. It estimates the probability that something belongs to one of two groups, such as whether a loan will be repaid. Banks like it because each input’s effect on the result is easy to explain.

Decision Trees and Random Forests

A decision tree splits data with a series of yes/no questions, like a flowchart. It is easy to read but can overfit. A random forest fixes this by training hundreds of trees on different slices of the data and combining their votes, which usually makes it far more accurate.

Support Vector Machines (SVM)

An SVM finds the boundary that separates two classes with the widest possible gap. It works well on smaller datasets with many features, such as text classification.

K-Nearest Neighbors (KNN)

KNN classifies a new item by looking at the most similar items it already knows. If most of a new customer’s five nearest neighbors bought a product, KNN predicts they will too. It needs no training step but gets slow on large datasets.

K-Means Clustering

K-means is an unsupervised algorithm that sorts data into a set number of groups, where items in each group are similar to each other. Marketers use it for customer segmentation.

Gradient Boosting

Gradient boosting builds trees one after another, with each new tree correcting the previous tree's errors. Libraries such as XGBoost and LightGBM make it one of the most accurate choices for spreadsheet-style business data.

Neural Networks

Neural networks pass data through layers of connected nodes, loosely inspired by the brain. They learn by adjusting the strength of each connection to reduce errors. Deep neural networks power image recognition, speech recognition, and generative AI, but they need lots of data and are hard to interpret.

Types of Machine Learning Models

Machine learning models are usually grouped by the job they do. MathWorks names classification and regression as the two main types (MathWorks). Add clustering and deep learning, and you cover most models in use today.

Classification Models

Classification models put things into categories. Binary classification picks between two options, such as fraud or genuine. Multiclass classification picks from several, such as sorting support tickets into billing, technical, or sales. Common algorithms include logistic regression, random forests, and SVMs.

Regression Models

Regression models predict a number on a continuous scale. Examples include forecasting next quarter’s revenue, estimating delivery times, or predicting energy demand. Linear regression and gradient boosting are frequent choices.

Clustering Models

Clustering models group similar items without being told what the groups should be. They are used for customer segmentation, organizing documents by topic, and spotting outliers that fit no group.

Deep Learning Models (CNNs, RNNs and Transformers)

Deep learning models handle complex, unstructured data:

  • Convolutional neural networks (CNNs) are built for images and video, such as detecting tumors in scans or reading license plates.
  • Recurrent neural networks (RNNs) process sequences, such as time series or older speech systems.
  • Transformers process whole sequences at once and power modern language models, translation tools, and chatbots.

How to Choose the Right Machine Learning Model

Start with the simplest model that could work, then add complexity only if results demand it. Use these four questions:

  1. What do you want to predict? A category points to classification. A number points to regression; no target at all points to clustering.
  2. How much labeled data do you have? Thousands of labeled rows suit classic algorithms. Millions of images or documents suit deep learning.
  3. Do you need to explain the decision? In lending or healthcare, you may need a readable model like logistic regression or a decision tree.
  4. How fast must it run? A model that answers in milliseconds on a phone needs to be smaller than one that runs overnight on a server.

In practice, a strong approach is to train a simple baseline first, then compare it with a random forest or gradient boosting model. Move to deep learning only if the gain is worth the extra cost.

Benefits and Limitations of Machine Learning

Machine learning is powerful when you have good data and a repeatable decision. It struggles when data is poor, the situation is rare, or a wrong answer is costly.

Benefits

Limitations

Handles volumes of data no team could review by hand

Only as good as its training data, including its biases

Finds patterns people would miss

Complex models can be hard to explain

Improves as it sees more data

Can fail quietly when real-world data shifts

Automates repetitive decisions at scale

Needs ongoing monitoring and retraining

Personalizes experiences for each user

Raises privacy and fairness questions

The biggest risk is overconfidence. A model will always answer, even when the input looks nothing like its training data. That is why sensitive uses, such as lending, hiring, and healthcare, keep a person in the loop and test models for fairness before launch.

Frequently Asked Questions

The four main types are supervised, unsupervised, semi-supervised and reinforcement learning. Many experts now add self-supervised learning as a fifth type, because it powers large language models.
Yes. ChatGPT is built on a transformer, a type of deep learning model. It was pre-trained with self-supervised learning on large amounts of text, then refined with human feedback through reinforcement learning.
An email spam filter is the classic example. It learns from emails labeled as spam or not spam, then sorts new messages automatically. Each time you mark an email as spam, you give it more training data.
The core ideas are easy to grasp, as this guide shows. Building models yourself takes some Python, basic statistics and practice. Free tools such as scikit-learn let beginners train their first model in a few lines of code.
Vipinraj Nair

About the Author

Vipinraj Nair LinkedIn

Founder & CEO

Vipinraj Nair is the Founder and CEO of Cypherox Technologies, which he started in 2015. He leads the company's work across custom software, web and mobile development, and AI solutions for startups, SMEs, and enterprises worldwide. He writes on technology trends, custom development, and how businesses put emerging tech to practical use.